Archon
A design-review sparring partner distilled into Qwen3-8B with QLoRA, small enough to run on an 8 GB laptop GPU. Judged blind against the base model and on benchmarks, with the honest result that it learned the style but lost accuracy.
The problem
I wanted a model that pushes back on software designs the way a senior reviewer does, and I wanted to know honestly whether fine-tuning a small open model gets you there.
How it works
- Knowledge distillation: a larger Qwen 32B teacher wrote step-by-step reasoning for each answer in the training chats, and the smaller student learned from it.
- Fine-tuned the Qwen3-8B student with QLoRA on a 24 GB NVIDIA L4. The quantized Q4_K_M build runs on an 8 GB laptop GPU at about 42 tokens per second.
- Compared it with the base model in blind pairwise chats, where the judge doesn’t know which answer came from which model.
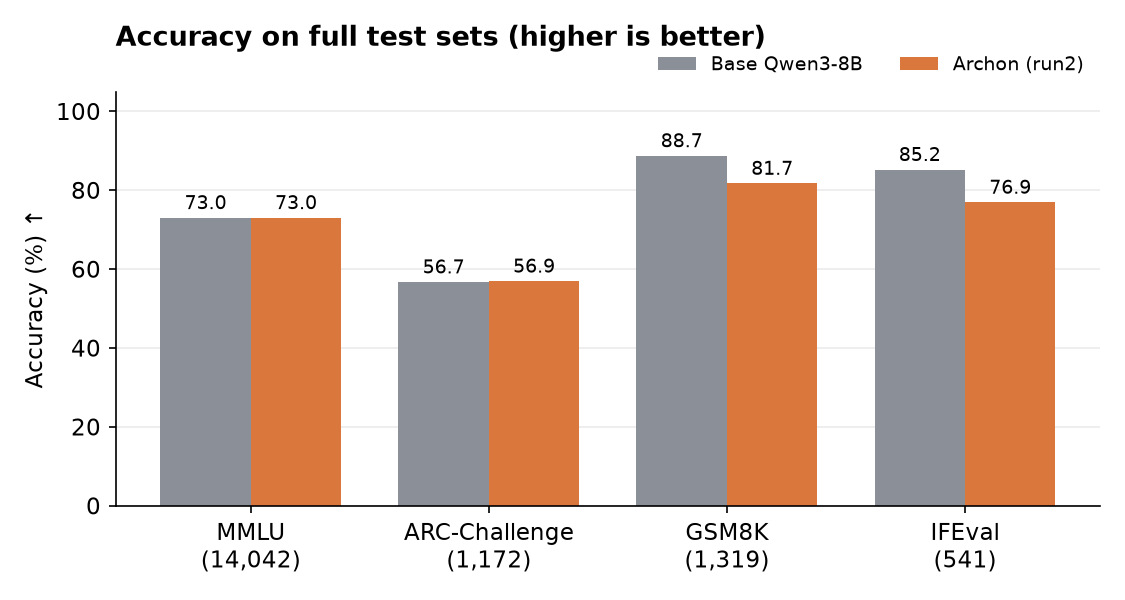
- Ran standard benchmarks on both: MMLU, ARC-Challenge, GSM8K and IFEval.
Results
- Blind comparison over 186 chats: Archon won 38, the base model won 125, and 23 were ties.
- MMLU stayed at 73.0 and ARC-Challenge moved from 56.7 to 56.9, but GSM8K dropped from 88.7 to 81.7 and IFEval from 85.2 to 76.9.
- Answers got about 3x shorter: 281 tokens per GSM8K answer against 896 for the base model, which is roughly 7 seconds instead of 21 on the laptop.
It picked up the reviewer’s style and answers much faster, but lost accuracy, and the evaluation is set up so that shows clearly.